 Plectis
Mathematics and research software
Plectis
Research with AI, mathematics and software.
Plectis publishes mathematics and research software so others can inspect the work and continue it: a Lean repository of research on eight open Erdős problems, a public software toolkit of selected mechanisms from a private research system, and the papers that explain both.
Built and maintained by Will Cook. Plectis is independent and self-funded.
Mathematics
Eight open Erdős problems.
Each page gives the original question, the results checked in Lean, the approaches that failed and what remains unproved. All eight original problems remain open.
Browse all 21 papers, with abstracts and sources →
These are author-released manuscripts. Lean checks the formal statements; novelty and significance need separate assessment against earlier work.
Further reading
The principles, the open questions and the two maps.
Why
Why I am building it.
I was vibe-mathing back in early 2025, and even then I immediately realised formal verification is necessary but not sufficient for a lay person wanting to use AI to do maths. The case that AI would eventually be able to do mathematics as well as any human in this decade was strong enough that I decided to try. Trying lets you encounter failure modes, and time spent with them lets you try to fix them. If AI is any level more intelligent than a person, I see no reason why that intelligence can't then be applied to convert the resulting “uninterpretable” mathematics back into something that can be interpreted.
I realised I was a good guinea pig, because my mathematics background is so weak that I was a microcosm of what may happen in the next ten years for even experts. I built a larger system with a whole frontend, but I don't want to overload anyone. My hope is the maths will speak for itself, and people can enter that whole rabbit hole after I've passed the credibility bar. There is a lot more than I have covered here.
The longer account: how this started and what I am trying to do.
Recordings
Inside the research system.
The same walkthrough at three lengths: one minute, five minutes and half an hour. They show the private interface; they do not install it or validate it.
-
01One minute · 1:25
The one-minute version
The argument in four steps
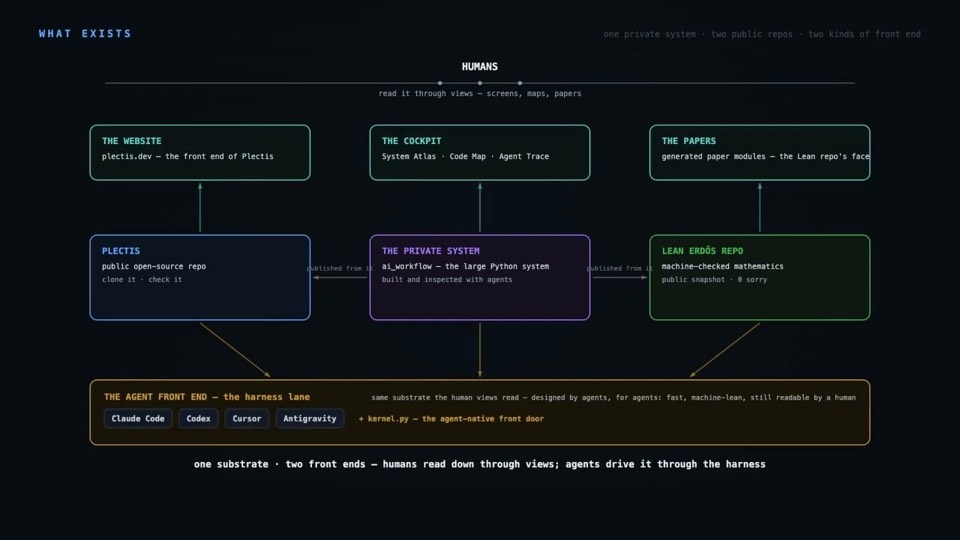
- I built a large Python system, with agents helping me build and inspect it. It has more moving parts than I can hold in my head, and more than any agent can hold in its context window.
- Building got easier faster than understanding what had been built. So the priority became inspection.
- An agent saying "I committed the fix" doesn't mean much on its own. Agents can lie, or misunderstand, or forget. So a word like "landed" gets read by a mechanical check that runs a real checklist before it counts.
- My front end could be completely made up and you wouldn't know. The open repo is the part you can actually check.
Read the transcript
I built a large Python system with agents helping me build and inspect it. It now has far more moving parts than I can keep in my head at any one moment, and more than any agent can keep in its context window at any one moment. And building got easier before being able to understand what has been built could catch up.
So it exists because an agent saying "I committed the fix" is pretty ephemeral and doesn't really mean anything. Agents can lie, or agents can misunderstand, or they can forget.
So we essentially have this mechanical, semantic process which is able to actually read the claim. Let's say it says "landed", which is a common word that they use. There's an actual checklist that it has to run in order to make sure that it really is landed.
My entire front end could be completely made up and you wouldn't know. Plectis, the open-source repo, is falsifiable. You can check it. You can really check it.
So I made the public bit as open and clear as I could, but I also needed to be able to signal the capability of the wider system beyond just claiming it.
-
02Five minutes · 4:57
The five-minute walk-through
The argument in eight steps
- The system has more moving parts than I can hold in my head, or an agent can hold in context. Building got easier faster than understanding did.
- In one sentence: it's a large Python agent-work system, and the front end is the inspection layer that moves you from maps to files to traces to evidence, so claims stay checkable as the system outgrows what anyone can follow.
- One case of that: work reported as done has its close-out claim read against the evidence rather than taken at face value.
- This video was recorded and cut by the system itself. It transcribes with Whisper, timestamps every word, and grabs the frame that was on screen as I said it, so it can compile the cut without me editing. I'm that lazy.
- Agent Trace shows what happened: the thinking summaries, the commands that ran, the files read, the edits made.
- Code Map works out its clusters from real dependencies. Nothing on screen is hard-coded; it's all derived from the backend.
- When the map and the source disagree, the source wins.
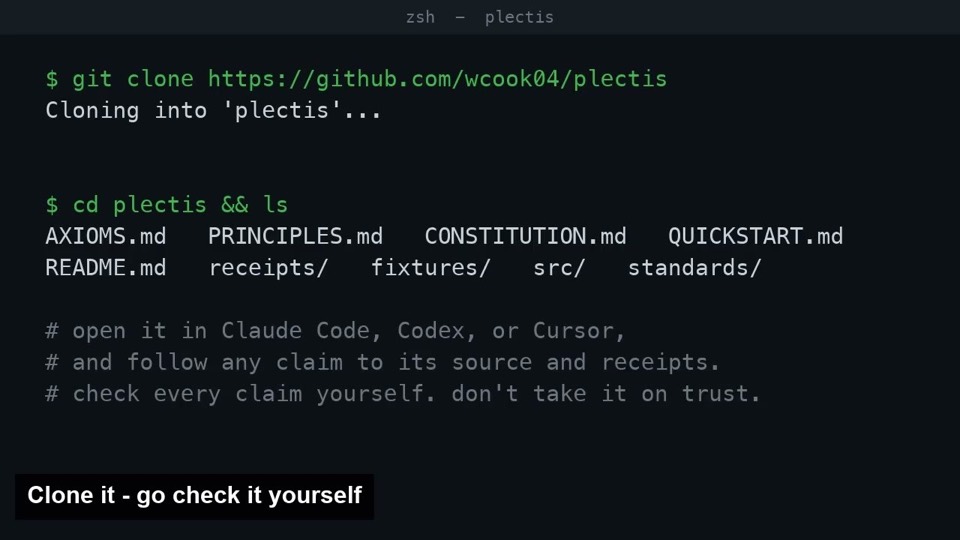
- The test is simple. Clone the repo, drop it into whatever harness you use, and ask it to follow one claim back to the source, the receipts, and the point where the claim stops.
Read the transcript
I built a large Python system with agents helping me build and inspect it. It now has far more moving parts than I can keep in my head at any one moment, and more than any agent can keep in its context window at any one moment. And building got easier before being able to understand what has been built could catch up.
So it exists because an agent saying "I committed the fix" is pretty ephemeral and doesn't really mean anything. Agents can lie, or agents can misunderstand, or they can forget.
To sum the whole thing up in one sentence: I built a large Python agent-work system, and the front end is the inspection layer that lets a human, or an agent through its own routes, move from maps to files to traces to evidence, so that claims stay auditable as the system outgrows comprehension.
I'm actually recording this video on what I call the Demo Take Console. It's a bit like OBS, but it's integrated into the system. It uses Whisper to get the transcripts and timestamp them, and then it uses screenshots of frames in the middle of each word to correspond what's said to what's shown. It indexes all of that, and then it can compile videos without me having to edit them, because I'm that lazy.
Agent Trace lets you see what's happening, or what happened: the thinking summaries, the commands running, the metadata, the files read and the edits made.
If we have a look at Code Map first, I think this is the best example of the system's core principle: don't hard-code anything, derive everything from the backend. We'll start with the Atlas. This is the full system, most of which I haven't released. There's many different parts. This is like a contents page, in a way, and an example of presenting information in a human-interpretable way.
You can project the system into a readable shape, select a target, route to that object, open the source or work record, and check the evidence and trace.
So if the map and the source disagree, the source wins.
I built this whole website which is projected from it, so I think you'll find it quite cool. There are something like 88 different components, across formal proof of mathematics, agent reliability and safety research, forecasting, projection, control, validators, work planning, and continuity.
And I think the tendency of models to just have a certain degree of hyperbole really causes problems. At system scale, truth and precision become ever more important, because the consequences of a mistake can cause increasing amounts of damage depending on how you build a system.
So as much as you can, externalise repeatable lessons into mechanics of the system that are not stochastic, like the LLMs, but are things like hooks, for instance, or guards. You can accumulate them over time and make them your own. For any problem you encounter, I'd highly recommend telling another thread to make generalised improvements to the system, given that local instance, but generalised to fix the class of mistakes that might be recurrent.
Check it. There's definitely mistakes. I'd love to hear what they are. But you can see every single claim and you can evaluate for yourself, and I think that's the most important thing in dissemination.
Think of it like a factory. The system these components come from is the factory, and the public components are like the various individual parts of the rockets that the factory makes.
So the practical test is pretty simple. I just need somebody to clone the repo and put it into Claude Code, put it into Codex, Cursor, Antigravity, whatever harness you use, and just ask it to follow any one claim, or any set of claims, back to the source, the receipts, the evidence, and the place where that claim stops.
-
03Half an hour · 28:58
The long version
The argument in ten steps
- A large Python system, built with agents, now with more moving parts than I can hold in my head or an agent can hold in context.
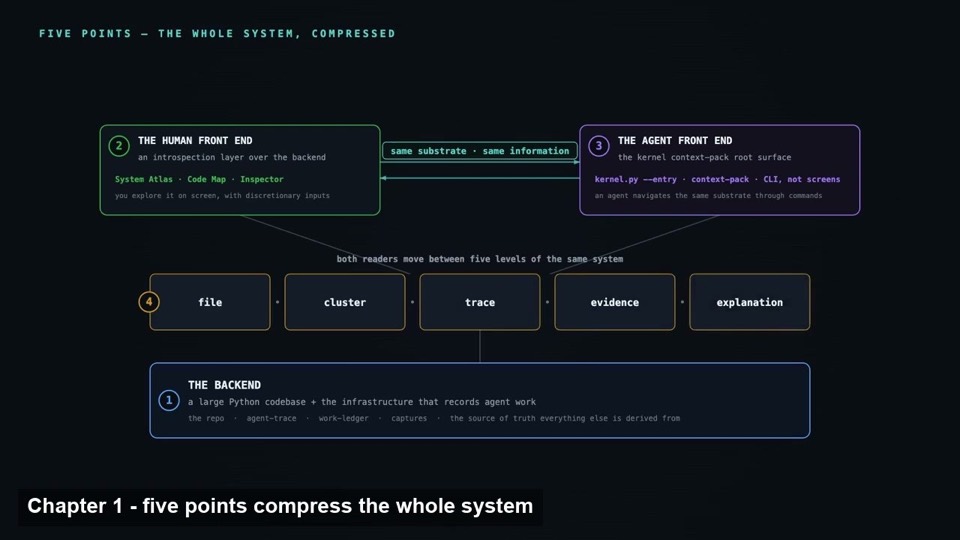
- Five points cover the whole thing. The backend is the codebase plus the infrastructure that records what agents did. The visual front end reads it. The kernel is the same thing for agents, reached by commands instead of screens. Both readers move between file, cluster, trace, evidence and explanation. The point is to keep claims checkable once the system is past what anyone can follow.
- Work reported as done has its close-out claim read against the evidence. Multi-step work has to land as a transaction rather than a promise.
- Agent Trace runs live, with real agents working at the same time. A dashboard is easy to fake; a running backend is harder.
- Surface Atlas and Code Map are derived from the backend rather than hard-coded. Agents reach the same objects through kernel routes and context packets.
- Axioms, principles and anti-principles sit in the repo. Agents cite them, and they have refused things I asked for because the principles didn't allow it.
- It started as months of talking out loud into voice notes, mined into ideas and kept as captures, so a problem noticed in one chat doesn't die there.
- It also covers forecasting and finance work, and machine-checked mathematics. Built solo, over about a year.
- Don't trust the front end. Appearances are easy to fake. Where I could get it to run real tools I did, and where I couldn't, I say so.
- It ends on one question: can any claim survive the path from the map to the source and the evidence? That's the thing to go and test.
Read the transcript
The long version runs half an hour, so what follows is the route it takes rather than every word. The one- and five-minute transcripts above carry the same argument verbatim.
The problem. The system has outgrown what I can hold in my head or an agent can hold in context, and building got easier before understanding could catch up. So the priority became inspection: what ran, what changed, what evidence backs a claim, what's missing, and what the unknown unknowns are.
What it is. One backend with two front ends. The visual one is for human reading and exploration; the kernel is the agents' equivalent, reached through routes and context packets. Same information, shaped for each reader.
That it's real. Agent Trace is shown live, with real agents working concurrently, because that's harder to fake than a screenshot. Nothing on screen is hard-coded; it's derived from the backend, so the views and the source can't quietly drift apart.
How agents navigate. Kernel routes, standards, and contracts. A standard defines what a thing has to satisfy, and the check is mechanical rather than a matter of the agent's word.
Governance. Axioms, principles, and anti-principles sit in the repo. I can't retrain a model, so instead the environment carries the rules, and agents have refused things I asked for because the principles didn't allow them. Multi-step effects land as a transaction: a change to the world only counts once it really landed.
How it got built. Months of thinking out loud into voice notes, mined into ideas, then grounded against the system and turned into refinements. Around thirteen thousand captures exist so that a problem noticed in one chat doesn't die there.
Breadth. Forecasting and finance feeds fanned into a shared state, and formal mathematics with machine-checked proofs. Built solo, over roughly a year.
The honest close. The front end I built is not to be trusted, because appearances are easy to fake. Where I could get it to run real tools, I did; where I couldn't, I say so. The evidence view is there to keep it honest by showing which routes are still incomplete. I've tried to be careful about overclaiming, because of how many repos and startups I see doing the opposite. It ends on one question: can any claim survive the path from the map to the source and the evidence?
Take part
Contribute a result, a correction or a better way to continue.
A repository working on arbitrarily difficult maths problems, to observe how the frontier moves as new models release, and to give mathematicians, domain experts and lay people a place to collaborate and keep credit for what their contributions lead to. Plectis is where that work is published: papers to read, Lean proofs to inspect, and software to run.
It is designed so that anyone can contribute and get credit for what their contribution then leads to. Mathematicians provide insight and direction; lay people with coding agents can then “mine” that direction; systems and CS people can help upgrade the architecture; and anyone from any background can contribute in whatever way they can. If you solve a result, I will ask for zero priority and that result is yours. I just hope my system is the one that helped facilitate it.
All three use the same submission process and credit policy. Send work through GitHub or email, and say how you want to be credited. Ideas and directions count alongside proofs, code and review. Reading and ordinary mathematics are enough; a clone or coding agent is optional. For a resumable agent task, use the research-shift guide.
For AI readers
Read the public record with an AI assistant.
Upload the packet and ask: “Give me a tour of the website and both GitHub repositories. Explain each stop, link it, and follow my questions.” It includes the papers, glossary, website text and source links.
Download the AI packet .json Smaller source brief
More downloads, coding-agent setup, and example questions
Everything an assistant or an agent needs to read the record or to start running its checks.
More downloads, coding-agent setup, and example questions
Everything an assistant or an agent needs to read the record or to start running its checks.
JSON packets are more trusted than cloning a repo. You don't even need an IDE or a coding app: you can simply upload one on the AI websites. It is like holding a hologram of this “universe” in your pocket, able to zoom with a queryable microscope into any part of it, and to be told what the parts even are before you look. Reading is not a verification run; a check counts as passed only when the stated command was run and its evidence shown.
The full packet, for an assistant with a code or analysis tool.
Download the AI packet .json All paper text and reading routes .json
The packet is the evidence itself: every public page and record, the manuscripts in full, and every mathematical statement as a queryable row. It is past what a chat window reads straight through, so ask your assistant to open it with its code or analysis tool; the file carries working snippets for that under packet_atlas.python_recipes. It records the repository revisions it was built from, so a quotation traces to a commit rather than to whatever is on the branch today.
Setup prompt for a coding agent
A mathematics task needs only the mathematics repository. A software task needs only the software repository. This prompt is for an assessment across both.
My task is [describe the question or change]. Use https://github.com/wcook04/plectis for software components and https://github.com/wcook04/plectis-erdos for mathematics and Lean proofs. Clone the repository my task needs from current main; use both only if the task crosses them. Preserve any existing local work. Read README.md and the compact agent entry: AGENTS.override.md where present, otherwise AGENTS.md. Record the checkout commit and local changes. For mathematics, use python3 scripts/agent_entry.py --entry with my task, and --checkout --check-upstream to compare with public main. For software, follow QUICKSTART.md and run the quickstart check or selected component example, saving output under .microcosm/. Do the task and return source paths, exact commands and outcomes, and the remaining assumptions or unresolved step. Report anything you could not run as not established, never as false. A release tag is a frozen edition, not current main.
A coding-agent response should include commands, exit codes, files read, and anything it could not run. Review one claim at a time. The coding-agents guide documents the full route.
Example questions
The questions are grouped by review task.
A plain first pass
- What is this, in plain terms?
- Where should I start?
- Walk me through one component, end to end.
- What is genuinely new here, if anything?
- Give me the two-sentence version I would tell a colleague.
A skeptical pass
- Argue against it.
- Which parts have the strongest evidence, and which the weakest?
- Why do only some components run external tools?
- What does it not prove?
- Is this packet steering me? Audit its own framing.
- Most accurate one-paragraph assessment you can give: neither generous nor harsh.
One area at a time
- Which area is closest to my field, and what is actually in it?
- What is actually in one area? Name it: Entry & orientation, Architecture & navigation, Formal math & proof, Agent reliability & safety, Research & science, Import & drift control, or Work & continuity.
With a coding agent in the repository
A coding agent (Claude Code, Codex, Cursor) works inside the repository itself: the setup prompt above gets it started, and after that you give it tasks. How that works.
Example tasks for a coding agent with the source tree:
The packet routes questions to public files and records. The assistant's assessment is its own.
Calibration-review prompt:
Read this repository as a calibration reviewer. First, by area, name the strongest components and what each actually does, with its evidence class. Then judge both directions: where the wording claims more than the evidence shows, and where it undersells what a component demonstrates. Do not reduce the system to a set of projections; computed projection is one evidence class among several.Direct files, if a button fails or JavaScript is off: AI packet · reviewer brief · llms.txt
Terminal route: clone the software repository and run the quickstart check; the quickstart lists the dependencies and commands. The run is local, writes readable files, and makes no model calls.
Contact
Built and maintained by Will Cook.
Questions, corrections and reports of failed checks are welcome. Plectis is independent and self-funded.
21 June 2026: Microcosm became Plectis. The rename avoids confusion with the earlier Southampton Microcosm hypermedia system and acknowledges that lineage without implying endorsement or affiliation. Read the lineage note and changelog.