MedAgentBench study
- Their work
- MedAgentBench is by Jiang and coauthors at Stanford. It contains clinical tasks, de-identified patient records in a simulated record system, and a program that grades the answers an AI model gives.
- My work
- I ran a new experiment on one task, potassium replacement. I wrote the task’s instruction as a specification in Lean. I built 629 further cases from the benchmark’s own records, and ran three scripts and one AI model on them.
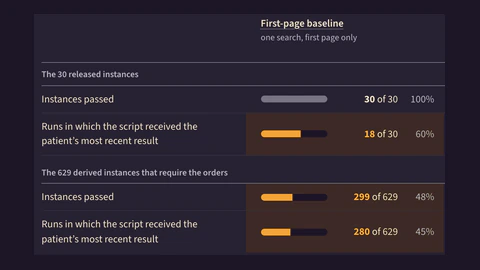
In the potassium task a model reads a patient’s most recent potassium result and submits two orders if it is low. A script that reads only the first page of search results passes Stanford’s grader on all 30 released cases, though on 12 of them that page does not contain the most recent result. On the 629 further cases, which all need the orders, the same script passes 299.
Limits: One task of the benchmark, and one AI model, DeepSeek V4.1 Flash. This is a prototype, and no one outside the study has reviewed it.
Lean is a program that checks mathematical proofs.